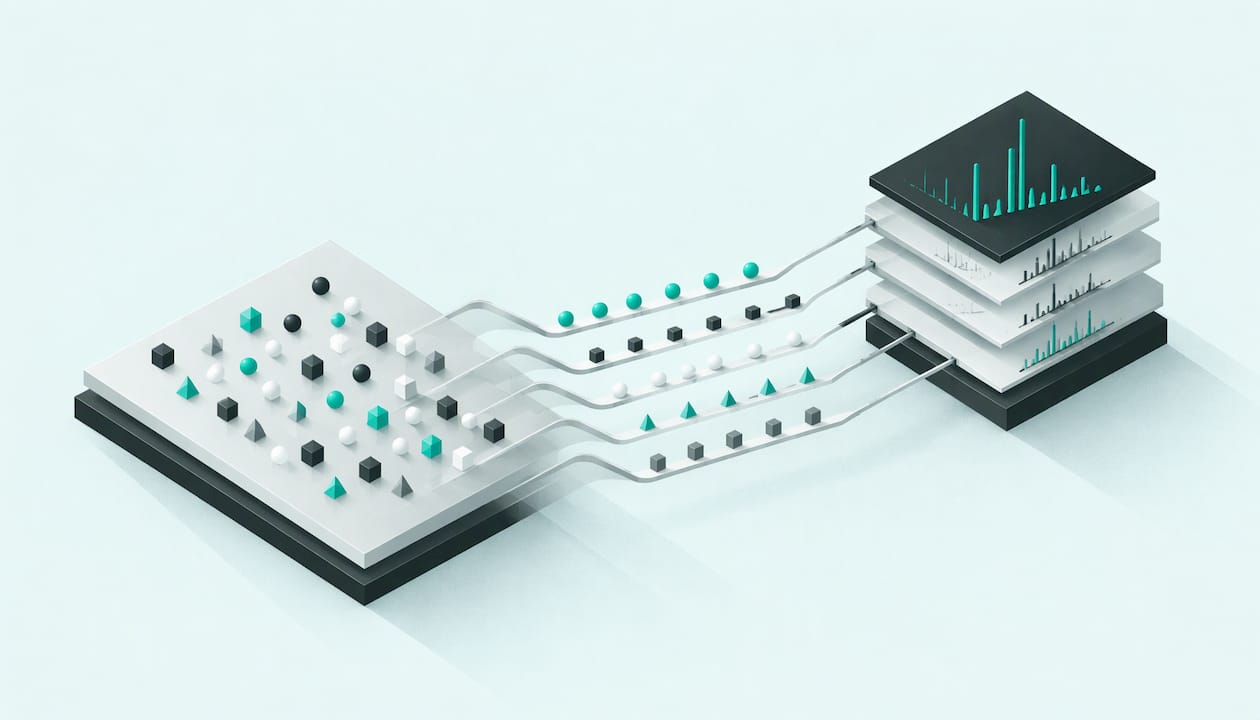
LC-MS peptide analysis separates a peptide mixture by liquid chromatography, then weighs and fragments the molecules in a mass spectrometer. The result tells you what is in the sample, whether the sequence is the one you expected, and how much of it is present. This guide walks through the workflow step by step, explains how MS/MS confirms a sequence, and shows how to judge whether a dataset deserves your trust. It is written for researchers and students working in UK laboratories.
TL;DR
- LC separates peptides by their chemistry, and MS measures their mass-to-charge ratio. Together they identify and quantify peptides in complex mixtures.
- MS/MS fragments a selected peptide so that the gaps between fragment peaks reveal the amino acid sequence.
- Peptide mapping uses digestion plus LC-MS to confirm the identity of a larger protein or peptide, and it needs expert review of the software output.
- Sample preparation, internal standards and search settings change the result as much as the instrument does.
- Pair mass data with a purity report: read the Certificate of Analysis alongside your own spectra.
Table of Contents
- What LC-MS peptide analysis actually measures
- From sample to spectrum: the workflow
- How MS/MS confirms a peptide sequence
- Peptide mapping for identity confirmation
- Quantifying peptides by LC-MS
- Reading the results with care
- Our perspective
- A practical verification checklist
- Research peptides for your LC-MS workflow
- FAQ
- Sources
What LC-MS peptide analysis actually measures
Two separate measurements sit inside one acronym. Liquid chromatography (LC) pulls a mixture apart over time, so that peptides reach the detector in a staggered sequence rather than all at once. Mass spectrometry (MS) then records the mass-to-charge ratio (m/z) of the ions that arrive.
In the classic bottom-up (or shotgun) proteomics set-up, proteins are digested into peptides, the peptides are separated by LC and analysed by MS, and the peptide sequence data are then used to work out which proteins were in the original sample. Peptide information is rolled up to the protein level for identification and quantification.
For a laboratory that buys a synthetic peptide, the question is usually simpler. You are not hunting through thousands of proteins. You want to know three things:
- Is the main species the right molecule (correct mass, correct sequence)?
- What else is in the vial (truncated sequences, modified forms, residual contaminants)?
- How much is there, if you need an accurate concentration?
LC-MS answers all three, which is why it is so widely paired with HPLC purity data. If you want the background on the chromatographic side, our comparison of HPLC and UPLC for peptide purity covers what changes with column technology.
From sample to spectrum: the workflow
A standard bottom-up workflow includes extracting proteins, fractionating to remove contaminants or proteins you are not interested in, digesting proteins into peptides, running post-digestion separations, and analysing the peptides by MS after further separation and ionisation. A pure synthetic peptide skips the extraction and often the digestion, but the logic of the later steps is the same.

Sample preparation
Preparation is where many datasets are won or lost. Practitioner-focused guidance describes sample preparation as a critical step that can significantly influence overall sensitivity on any given mass spectrometry platform.
For research peptides, three practical points matter most:
- Dissolve completely. A peptide that is only partly in solution gives a low and irreproducible signal. Charge and hydrophobicity guide the solvent choice, and our peptide solubility guide sets out the method.
- Remove salts that suppress ionisation. Residual salts and non-volatile buffers compete with the peptide in the source. Our article on desalting peptides covers the common methods and pitfalls.
- Watch for aggregation. Aggregated peptide can look like a loss of material or produce odd peaks. See our notes on peptide aggregation for detection and prevention.
Good handling before the sample reaches the autosampler also protects the result. The peptide handling guidelines for UK research labs cover storage, weighing and reconstitution.
Liquid chromatography
Most peptide work uses reversed-phase LC: peptides stick to a hydrophobic column and are eluted with a rising proportion of organic solvent. Each peptide has a characteristic retention time, which is a useful identity check in its own right. A shift in retention time between runs is a sign that something in the system or the sample has changed.
Reproducibility here can be excellent. In a micro-flow LC-MS/MS study covering more than 2000 samples, median chromatographic retention time variation was below 0.3% CV, with protein quantification CV below 7.5%. That level depends on a carefully designed method, but it shows what a well-controlled system can deliver.
Chromatography also separates the main peptide from closely related impurities, such as deletion sequences, before they reach the detector. This is why a clean LC trace and a clean mass spectrum together say more than either alone.
Ionisation and the mass spectrometer
As peptides leave the column they are ionised, usually by electrospray, and acquire several positive charges. A peptide therefore often appears as a series of peaks at different charge states, such as 2+, 3+ and 4+, all pointing to the same neutral mass. Reading that series correctly is a skill in itself, and our practical guide to reading mass spectra of peptides walks through it.
A first MS scan (MS1) gives the m/z of the intact ions. That is enough to check the molecular weight against the theoretical value. For sequence-level confirmation you need tandem MS, covered next.
How MS/MS confirms a peptide sequence
In LC-MS/MS the instrument isolates a precursor ion from a chromatographic peak and subjects it to collision energy. The fragments are recorded, and the distances between MS/MS peaks are used to infer the sequence.
The detail is tidy. The parent ion is fragmented and the second stage records the m/z of the product ions. Cleavage at peptide bonds yields fragment ions, including b-ions from the N-terminus and y-ions from the C-terminus, which enables sequence deduction. Each step along a b or y series corresponds to the mass of one amino acid residue, so you can read the sequence like a ladder.
Database search versus de novo
There are two main ways to interpret the spectra:
- Database search. The experimental spectrum is compared computationally with theoretical spectra predicted for candidate peptides. This is the usual route, and identification may also use de novo approaches or a combination of both.
- De novo sequencing. The sequence is read directly from the fragment ladder, with no database. It becomes important when matches are ambiguous, for example when proteins carry PTMs or splice variants, or when the genome is unknown. Automatic searches can misidentify peptides and miss analytes in those cases.
For a synthetic research peptide the expected sequence is known, so the practical task is confirmation: do the observed fragments match the theoretical b and y series, and are there unexpected fragments that suggest a modification? Our article on de novo peptide sequencing explains when it is worth going further than a database match.
Peptide mapping for identity confirmation
Peptide mapping is the approach of choice when the molecule is large enough that you want to confirm it piece by piece. The protein or large peptide is digested with an enzyme, the fragments are separated by LC and each is identified by MS/MS. Coverage of the full sequence is the goal.
It is a well-established method for confirming protein identity in batch release testing and product characterisation of therapeutic proteins and vaccine antigens, although interpretation stays challenging because of large data volumes and software processing. Historically, mapping used enzymatic digestion followed by reversed-phase LC with UV detection. It has since evolved to incorporate MS for residue-level confirmation, and it still relies on MS/MS fragmentation and specialised software.
When would you choose mapping over analysing the intact molecule?
| Situation | Intact mass | Peptide mapping |
|---|---|---|
| Short synthetic peptide, known sequence | Usually enough for identity, with MS/MS for sequence | Rarely needed |
| Longer peptide or protein, sequence coverage needed | Confirms overall mass only | Confirms the sequence segment by segment |
| Suspected modification at a specific residue | Shows a mass shift, not its location | Can localise the modified residue |
| Routine batch-to-batch comparison | Fast check | Detailed comparison of digest profiles |
The same guidance on peptide mapping is candid about pitfalls. It lists misassignments driven by isobaric or near-isobaric dipeptides, software-induced artefacts such as artificial succinylation, and incorrect deamidation-site assignments from misread isotopic peaks. Its conclusion is that expert manual review is required. That is a good rule for any LC-MS dataset: the software proposes, a person decides.
Quantifying peptides by LC-MS
LC-MS can measure how much peptide is present as well as what it is, but quantification asks more of the method than identification does.
Digestion changes sensitivity. In a systematic study of salmon calcitonin, quantifying the undigested peptide after solid-phase extraction from plasma reached a lower limit of quantification of 10 pg/mL. Adding a tryptic digestion step raised it to 50 pg/mL, because of sample complexity and interference in the SRM transition. See the full study.
The internal standard matters. The same study compared eight internal standard approaches and concluded that the best choice, with or without digestion, was the stable-isotope-labelled form of the analyte. A labelled twin behaves like the analyte through extraction, chromatography and ionisation, so it corrects for losses and signal drift. Where you need absolute numbers, this is the standard to aim for. Our note on HPLC calibration peptides covers standards and system checks in more detail.
Acquisition mode sets the ceiling. SWATH-MS fragments ionised peptides within defined mass windows and scores them peptide by peptide, typically against spectral libraries. Peptide quantification with it is reported to be three- to 10-fold less sensitive than targeted approaches. For a single synthetic peptide, targeted methods such as SRM are the natural choice.

Reading the results with care
A clean-looking spectrum does not settle every question. Three limits are worth knowing before you draw conclusions.
Not every spectrum yields an answer. In shotgun proteomics, low-abundance proteins can give incomplete sequence ions and chemical noise, PTMs can alter fragmentation and lower spectrum quality, and missing database sequences can prevent correct assignment. A peptide can be assigned for only 10 to 50% of MS2 spectra collected. With a pure, known peptide your assignment rate is far better, but the reasoning carries over: unassigned spectra are normal, and they are not automatically a problem.
Missing values are common in label-free work. It is reported as common to have 20 to 40% of attempted intensity measures missing, because a peptide may be identified in some samples and not in others. Plan replicates accordingly.
Software choices change the output. A comparison of search engines for immunopeptidomics found that reported sequencing depth at a global FDR below 1% differed with search space and spectral ranking, and cautioned that the data should be interpreted with caution. Record the engine, version, database and FDR threshold with your results.
Confidence estimates help. One targeted feature detection approach reported feature-selection FDR estimates of about 1.5% on average for a full feature set and about 3% for features inferred from external peptide IDs, in a benchmark analysis. Numbers like these are only meaningful when you know how they were derived, so keep the method details with the data.
Our perspective
In our experience, the most useful LC-MS result is one you can check against something else. A mass spectrum on its own tells you the molecule has the expected mass. It does not tell you how pure the material is, and a chromatogram on its own does not tell you the sequence is right.
That is why we pair 99%+ HPLC purity with verification and detailed certification, including a Certificate of Analysis for our research peptides. Our aim is that a laboratory receives material it can characterise with confidence, and can set our documentation beside its own LC-MS data without surprises.
Our advice to any lab: confirm identity by mass, confirm sequence by MS/MS where the question matters, keep the raw files, and review software output by eye. Quality controls are only worth having when they are open to inspection, and we build our process around that principle.
Neil
A practical verification checklist
Use this order when you receive a research peptide and want to confirm it by LC-MS:
- Read the paperwork first. Note the stated molecular weight, sequence and purity. Our guide to the peptide Certificate of Analysis shows what each line means.
- Reconstitute carefully. Choose the solvent by charge and hydrophobicity, and use fresh, clean glassware and low-binding vials where adsorption is a concern.
- Run a blank, then the sample. A blank injection shows carry-over and background ions before you interpret any peak.
- Check retention time and the main peak. Compare it with earlier runs of the same material on the same method.
- Match the mass. Deconvolute the charge series and compare the neutral mass with the theoretical value. Look for sodium or potassium adducts, which can be mistaken for modifications.
- Run MS/MS on the main ion. Assign the b and y ions. Guidance on de novo work advises assigning all abundant fragment ions and considering instrument-specific and unusual fragments that are unique to certain sequences or modifications.
- Keep the evidence. Journals request assigned spectra and raw data for single-peptide identifications, and especially for PTM reports, so archive the raw files and annotated spectra from the start.
- Plan stability checks. If you will store reconstituted material, repeat the analysis over time. Our peptide stability testing guide outlines a practical design.
Research peptides for your LC-MS workflow
If you are building or validating an LC-MS method, you need a starting material you can document. BioForgeUK supplies precision research peptides with 99%+ HPLC purity, supported by stringent quality controls, advanced verification and detailed certification including Certificates of Analysis.

All of our products are supplied strictly for laboratory and scientific research use, not for human or veterinary consumption. You can read the terms on our research use only page, or browse the range from the BioForgeUK home page, where checkout is secure.
FAQ
What is the difference between LC-MS and LC-MS/MS for peptides?
LC-MS measures the m/z of intact peptide ions, which confirms molecular weight. LC-MS/MS adds a second stage in which a selected ion is fragmented and the fragment masses are recorded. That second stage gives sequence information, so it is the step to use when you need to verify the amino acid order.
Can LC-MS tell me how pure my peptide is?
It shows which species are present and their relative signals, which is valuable for spotting truncated or modified forms. Ionisation efficiency differs between molecules, so peak heights in MS are not a strict measure of purity. Purity is normally reported from HPLC with UV detection, and MS is used to identify what each peak is.
Do I need to digest a short peptide before analysis?
Usually not. Short peptides can be analysed intact, and digestion is mainly for proteins or long peptides. In the calcitonin quantification study, adding digestion raised the limit of quantification from 10 to 50 pg/mL, so skip it when the intact molecule works.
Why does my search software report a different result from my expected sequence?
Automated matching can misassign peptides, especially with modifications, near-identical residues or incomplete fragmentation. Check the annotated spectrum by hand and confirm which database, engine and FDR threshold were used. Ambiguous matches are exactly where manual validation and de novo reading are recommended.
What should I record so that my LC-MS data are reproducible?
Keep the raw files, the method (gradient, column, source settings), the internal standard used, the software version, the database and the FDR threshold. Record sample preparation details too, since preparation can strongly influence sensitivity. These details let a colleague, a reviewer or your future self repeat the analysis.
Sources
- Liquid chromatography mass spectrometry-based proteomics (PMC)
- Getting Started in Computational Mass Spectrometry-Based Proteomics (PLOS Computational Biology)
- Primer: Shotgun Proteomics in Neuroscience (PMC)
- The Hunt Lab Guide to De Novo Peptide Sequence Analysis (PMC)
- Peptide Mapping for Sequence Confirmation of Therapeutic Proteins (PMC)
- Data-independent acquisition-based SWATH-MS (PMC)
- High-Sensitivity LC-MS/MS Quantification of Peptides and Proteins (Analytical Chemistry)
- Robust, reproducible and quantitative analysis of thousands of proteomes by micro-flow LC-MS/MS (PubMed)
- The application of quantification techniques in proteomics for biomedical research (University of Manchester)
- The Choice of Search Engine Affects Sequencing Depth (PMC)
- Lessons in De Novo Peptide Sequencing by Tandem Mass Spectrometry (PMC)
- Targeted Feature Detection for Data-Dependent Shotgun Proteomics (Journal of Proteome Research)